Table of Contents
Abstract
The measurement of unobservable psychological, behavioral, and health-related phenomena requires robust methodological tools. Because researchers cannot directly observe Latent Constructs like depression, food insecurity, or self-efficacy, they rely on psychometric scales to capture these complex domains. However, creating a scientifically sound questionnaire is a rigorous, multi-stage endeavor that is often poorly understood or inadequately taught in graduate training programs. This comprehensive framework provides a structured, nine-step methodology for scale development and validation, designed to bridge the gap between advanced psychometric theory and applied research needs.
The framework divides the scale creation process into three overarching phases: item development, scale development, and scale evaluation. By systematically guiding researchers through domain identification, cognitive pre-testing, factor extraction, and rigorous reliability and Validity testing, this primer ensures that newly developed instruments are both theoretically grounded and statistically sound. Ultimately, adhering to these best practices minimizes measurement error and enhances the reproducibility and accuracy of scientific findings across the social and health sciences.
Authors
Purpose
In the rapidly evolving landscape of behavioral and health sciences, researchers frequently encounter novel research questions that require the measurement of new or highly specific Latent Constructs. Unfortunately, many investigators lack formal training in psychometrics, leading to the proliferation of poorly constructed, unvalidated questionnaires that compromise data integrity. This framework was developed to demystify the complex, jargon-heavy world of scale construction.
By distilling dense psychometric literature into an accessible, step-by-step guide, this primer serves as an essential roadmap for researchers and clinicians. It addresses a critical gap in methodological training, empowering investigators to either build rigorous new instruments from scratch or critically evaluate and adapt existing tools. This standardization of measurement practices is vital for advancing evidence-based practice and ensuring that clinical and research data accurately reflect the human experiences they intend to capture.
Construct
In psychometric theory, a latent construct represents a theoretical variable—such as an attitude, trait, or behavioral tendency—that cannot be directly observed or measured with a single metric. Because these phenomena are abstract, researchers must infer their presence and magnitude by measuring a set of observable indicators or behaviors that are theoretically driven by the underlying construct.
The scale development framework emphasizes that a construct must be unambiguously defined and its theoretical domain carefully mapped before any items are generated. This ensures that the resulting scale captures the entirety of the target phenomenon without bleeding into conceptually adjacent but distinct areas. By using multiple carefully crafted items to tap into different facets of the latent construct, researchers can isolate and account for item-specific measurement error, thereby producing a more precise and reliable composite score.
Validity
Validity testing is framed not as a single hurdle, but as an ongoing, cumulative process that begins at the very inception of a scale. The framework highlights content Validity as the foundational step, requiring expert and target population judges to evaluate whether the initial item pool adequately and exclusively represents the defined construct. This theoretical analysis ensures that the questions are highly relevant and comprehensive before any data is collected.
Once the scale is administered, the evaluation phase shifts to empirical forms of Validity, including criterion and construct Validity. Researchers are guided to examine how well their new scale correlates with established measures (convergent Validity), diverges from unrelated constructs (discriminant Validity), and predicts relevant outcomes. By triangulating these different forms of Validity evidence, developers can confidently assert that their instrument genuinely measures the specific latent dimension it was designed to assess, rather than capturing unintended variance.
Reliability
reliability is conceptualized as the degree to which an instrument yields consistent, stable results under identical conditions. The framework outlines several statistical approaches to quantify this consistency, emphasizing that a scale must be reliable before its Validity can be fully trusted.
While Cronbach's alpha remains the most ubiquitous metric for assessing internal consistency—indicating how well the items within a scale correlate with one another—the primer also introduces alternative and sometimes more robust estimates like McDonald's Omega and ordinal alpha for specific data types. Furthermore, the framework stresses the importance of test-retest reliability (the coefficient of stability) to demonstrate that the latent construct, assuming it is a stable trait, does not spuriously fluctuate across different time points. Together, these metrics ensure that the scale's scores are dependable and relatively free from random measurement error.
Factor Analysis
Factor extraction is a critical analytical phase where the underlying, latent structure of the item pool is empirically revealed. Using Factor analysis, researchers regress observed item responses onto unobserved latent factors to determine how many distinct dimensions are necessary to explain the shared variance among the items. This process helps identify which items strongly cluster together and which ones fail to contribute meaningfully to the measurement model.
The framework advises researchers to use multiple criteria—such as scree plots, variance explained, and parallel analysis—to determine the optimal number of factors to retain. Items that demonstrate weak relationships with the latent factor (typically those with factor loadings below 0.30, which explain less than 10% of the variance) are flagged for removal, while it is generally recommended to retain items with loadings of 0.40 or higher. For unidimensional models utilizing Rasch Item Response Theory, developers should look for mean-square residual summary statistics (infit and outfit) falling between 0.4 and 1.6 to indicate good item fit. Following this exploratory reduction, the framework mandates a rigorous test of dimensionality, often using confirmatory Factor analysis on an independent sample, to verify that the hypothesized factor structure holds true.
Instrument
| Test Type | Self-report questionnaire |
| Population | General population |
Figures
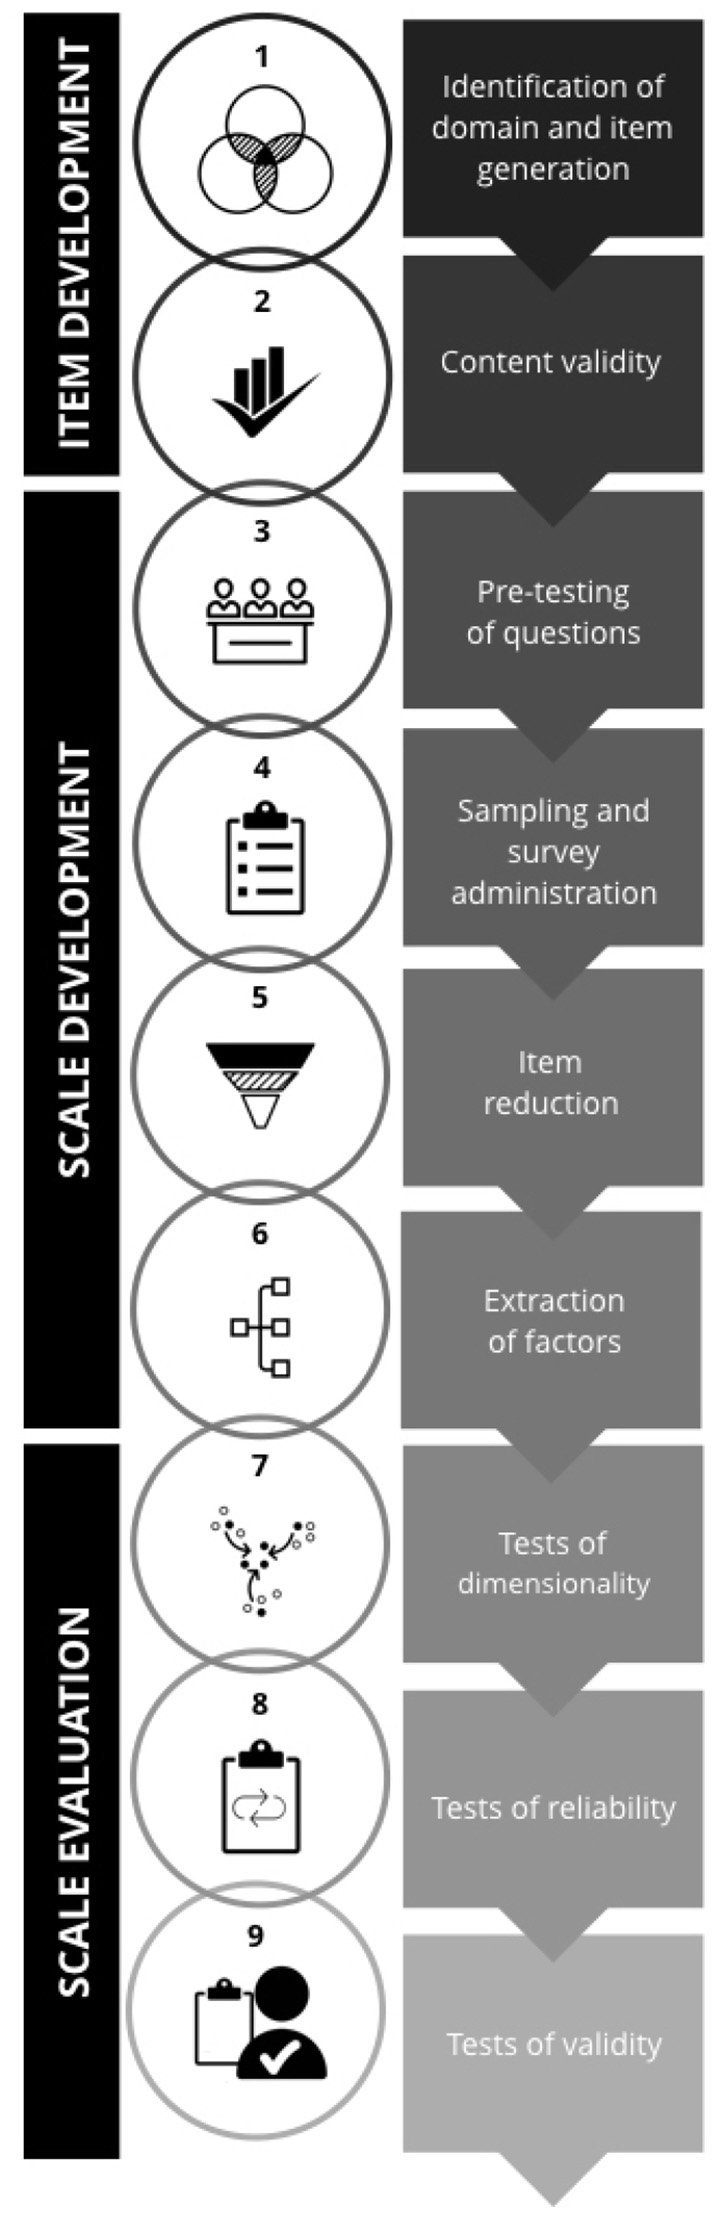
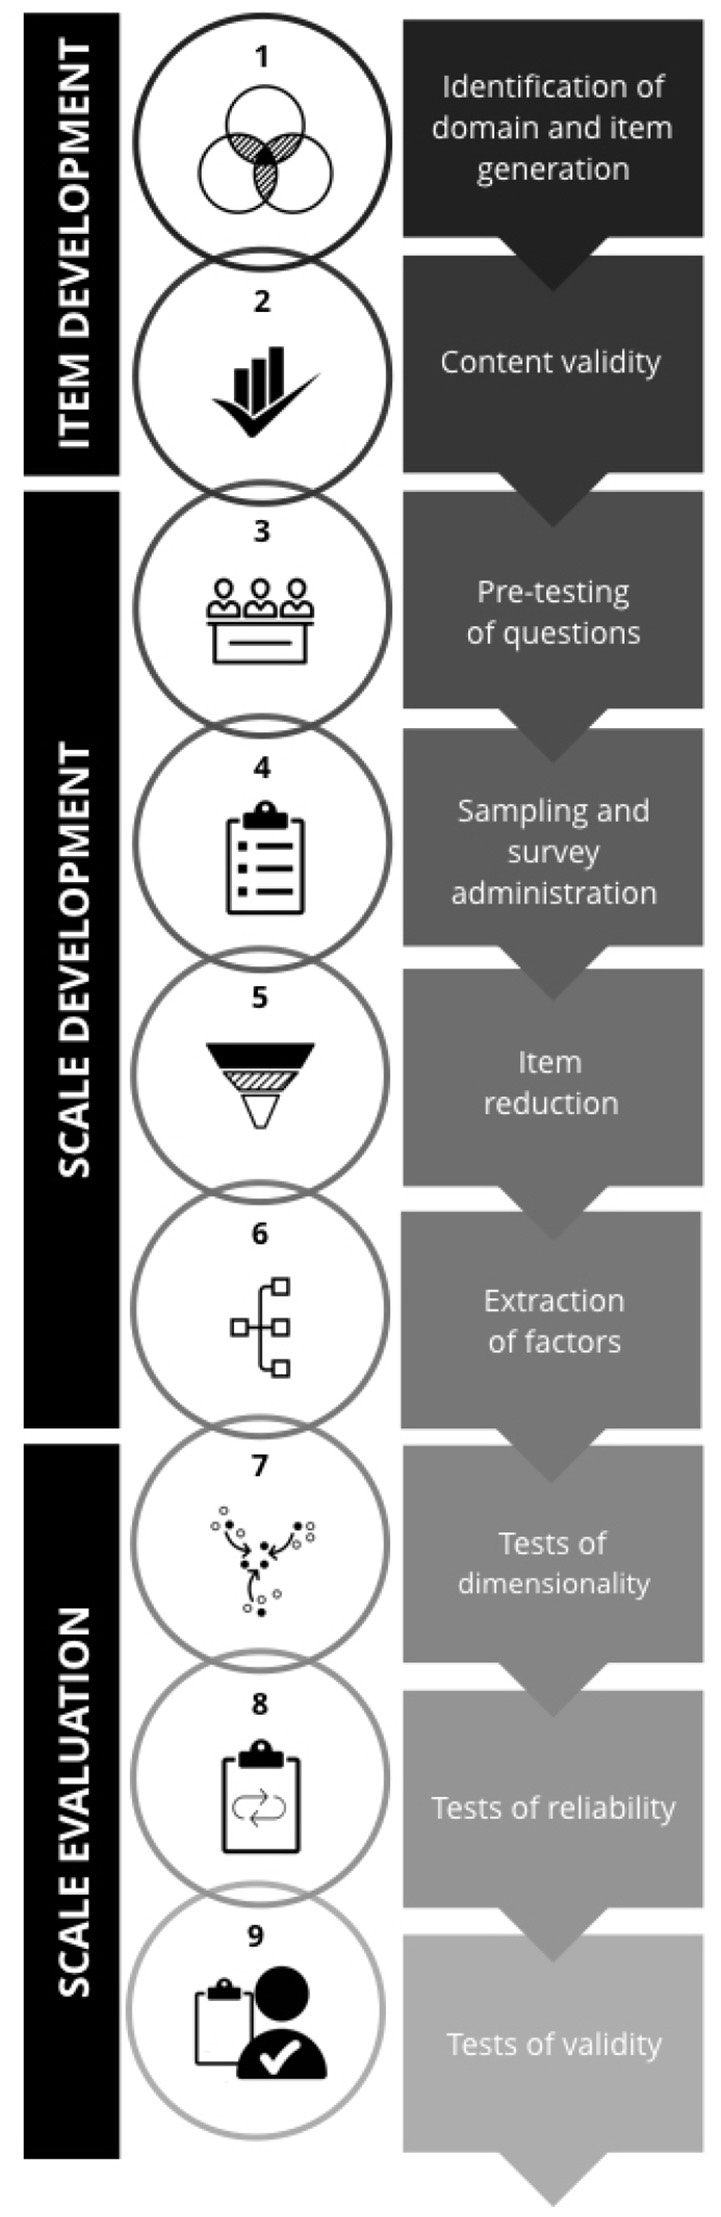
Best Practices for Developing and Validating Scales (Primer) Items
Items are currently not available
The individual items of this scale are not publicly available. Researchers interested in using this instrument should contact the original authors directly to request the scale materials.
Cite This Paper
Godfred O. Boateng, Torsten B. Neilands, Edward A. Frongillo, Hugo R. Melgar-Quiñonez, Sera L. Young (2018). Best Practices for Developing and Validating Scales (Primer). Frontiers in Public Health. https://doi.org/10.3389/fpubh.2018.00149
References
141 references
- DeVellis (2012). scale development: Theory and Application.
- Raykov (2011). Introduction to Psychometric Theory. 🔗 https://doi.org/10.4324/9780203841624
- Streiner (2015). Health Measurement Scales: A Practical Guide to Their Development and Use, 🔗 https://doi.org/10.1093/med/9780199685219.001.0001
- McCoach (2013). Instrument Development in the Affective Domain. School and Corporate Applications, 3rd Edn. 🔗 https://doi.org/10.1007/978-1-4614-7135-6
- Morgado (2018). scale development: ten main limitations and recommendations to improve future research practices. Psicol Reflex E Crtica, 30 3. 🔗 https://doi.org/10.1186/s41155-016-0057-1
- Glanz (2015). Health Behavior: Theory, Research, and Practice.
- Ajzen (1985). From intentions to actions: a theory of planned behavior. 11.
- Bai (2008). Validation of a short questionnaire to assess mothers' perception of workplace breastfeeding support. J Acad Nutr Diet, 108 1221. 🔗 https://doi.org/10.1016/j.jada.2008.04.018
- Hirani (2013). Perceived Breastfeeding Support Assessment Tool (PBSAT): development and testing of psychometric properties with Pakistani urban working mothers. Midwifery, 29 599. 🔗 https://doi.org/10.1016/j.midw.2012.05.003
- Boateng (2018). Matern Child Nutr., 🔗 https://doi.org/10.1111/mcn.12579
- Arbach (2014). reliability and Validity of the center for epidemiologic studies-depression scale in screening for depression among HIV-infected and -uninfected pregnant women attending antenatal services in northern Uganda: a cross-sectional study. BMC Psychiatry, 14 303. 🔗 https://doi.org/10.1186/s12888-014-0303-y
- Natamba (2015). reliability and Validity of an individually focused food insecurity access scale for assessing inadequate access to food among pregnant Ugandan women of mixed HIV status. Public Health Nutr., 18 2895. 🔗 https://doi.org/10.1017/S1368980014001669
- Neilands (2010). Development and validation of the sexual agreement investment scale. J Sex Res., 47 24. 🔗 https://doi.org/10.1080/00224490902916017
- Neilands (2002). A validation and reduced form of the female condom attitudes scale. AIDS Educ Prev., 14 158. 🔗 https://doi.org/10.1521/aeap.14.2.158.23903
- Lippman (2016). Development, validation, and performance of a scale to measure community mobilization. Soc Sci Med., 157 127. 🔗 https://doi.org/10.1016/j.socscimed.2016.04.002
- Johnson (2007). The role of self-efficacy in HIV treatment adherence: validation of the HIV treatment adherence self-efficacy scale (HIV-ASES). J Behav Med., 30 359. 🔗 https://doi.org/10.1007/s10865-007-9118-3
- Sexton (2006). The Safety Attitudes Questionnaire: psychometric properties, benchmarking data, and emerging research. BMC Health Serv Res., 6 44. 🔗 https://doi.org/10.1186/1472-6963-6-44
- Wolfe (2001). Building household food-security measurement tools from the ground up. Food Nutr Bull., 22 5. 🔗 https://doi.org/10.1177/156482650102200102
- González (2008). Development and validation of measure of household food insecurity in urban costa rica confirms proposed generic questionnaire. J Nutr., 138 587. 🔗 https://doi.org/10.1093/jn/138.3.587
- Boateng (2018). A novel household water insecurity scale: procedures and psychometric analysis among postpartum women in western Kenya. PloS ONE., 🔗 https://doi.org/10.1371/journal.pone.0198591
- Melgar-Quinonez (2008). Measuring household food security: the global experience. Rev Nutr., 21 27s. 🔗 https://doi.org/10.1590/S1415-52732008000700004
- Melgar-Quiñonez (2005). Validación de un instrumento para vigilar la inseguridad alimentaria en la Sierra de Manantlán, Jalisco. Salud Pública México, 47 413. 🔗 https://doi.org/10.1590/S0036-36342005000600005
- Hackett (2008). Internal Validity of a household food security scale is consistent among diverse populations participating in a food supplement program in Colombia. BMC Public Health, 8 175. 🔗 https://doi.org/10.1186/1471-2458-8-175
- Hinkin (1995). A review of scale development practices in the study of organizations. J Manag., 21 967. 🔗 https://doi.org/10.1016/0149-2063(95)90050-0
- Haynes (1995). Content Validity in psychological assessment: a functional approach to concepts and methods. Pyschol Assess., 7 238. 🔗 https://doi.org/10.1037/1040-3590.7.3.238
- Kline (1993). A Handbook of Psychological Testing. 2nd Edn.
- Hunt (1991). Modern Marketing Theory.
- Loevinger (1957). Objective tests as instruments of psychological theory. Psychol Rep., 3 635. 🔗 https://doi.org/10.2466/pr0.1957.3.3.635
- Clarke (1995). Constructing Validity: basic issues in objective scale development. Pyschol Assess, 7 309. 🔗 https://doi.org/10.1037/1040-3590.7.3.309
- Schinka (2012). Handbook of Psychology, Vol. 2, Research Methods in Psychology.
- Fowler (1995). Improving Survey Questions: Design and Evaluation.
- Krosnick (2018). Questionnaire design. 439. 🔗 https://doi.org/10.1007/978-3-319-54395-6_53
- Krosnick (2009). Question and questionnaire design. 263.
- Rhemtulla (2012). When can categorical variables be treated as continuous? A comparison of robust continuous and categorical SEM estimation methods under suboptimal conditions. Psychol Methods, 17 354. 🔗 https://doi.org/10.1037/a0029315
- MacKenzie (2011). Construct measurement and validation procedures in MIS and behavioral research: integrating new and existing techniques. MIS Q., 35 293. 🔗 https://doi.org/10.2307/23044045
- Messick (1995). Validity of psychological assessment: validation of inferences from persons' responses and performance as scientifica inquiry into score meaning. Am Psychol., 50 741. 🔗 https://doi.org/10.1037/0003-066X.50.9.741
- Campbell (1959). Convergent and discriminant Validity by the multitrait-multimethod matrix. Psychol Bull., 56 81. 🔗 https://doi.org/10.1037/h0046016
- Dennis (1999). Theoretical underpinnings of breastfeeding confidence: a self-efficacy framework. J Hum Lact., 15 195. 🔗 https://doi.org/10.1177/089033449901500303
- Dennis (1999). Development and psychometric testing of the Breastfeeding Self-Efficacy Scale. Res Nurs Health, 22 399. 🔗 https://doi.org/10.1002/(SICI)1098-240X(199910)22:5<399::AID-NUR6>3.0.CO;2-4
- Dennis (2003). The breastfeeding self-efficacy scale: psychometric assessment of the short form. J Obstet Gynecol Neonatal Nurs., 32 734. 🔗 https://doi.org/10.1177/0884217503258459
- Frongillo (2006). Development and validation of an experience-based measure of household food insecurity within and across seasons in Northern Burkina Faso. J Nutr., 136 1409S. 🔗 https://doi.org/10.1093/jn/136.5.1409S
- Guion (1977). Content Validity – the source of my discontent. Appl Psychol Meas., 1 1. 🔗 https://doi.org/10.1177/014662167700100103
- Lawshe (1975). A quantitative approach to content Validity. Pers Psychol., 28 563. 🔗 https://doi.org/10.1111/j.1744-6570.1975.tb01393.x
- Lynn (1986). Determination and quantification of content Validity. Nurs Res., 35 382. 🔗 https://doi.org/10.1097/00006199-198611000-00017
- Cohen (1960). A coefficient of agreement for nominal scales. Educ Psychol Meas., 20 37. 🔗 https://doi.org/10.1177/001316446002000104
- Wynd (2003). Two quantitative approaches for estimating content Validity. West J Nurs Res., 25 508. 🔗 https://doi.org/10.1177/0193945903252998
- Linstone (1975). The Delphi Method.
- Augustine (2012). Psychometric validation of a knowledge questionnaire on micronutrients among adolescents and its relationship to micronutrient status of 15–19-year-old adolescent boys, Hyderabad, India. Public Health Nutr., 15 1182. 🔗 https://doi.org/10.1017/S1368980012000055
- Beatty (2007). Research synthesis: the practice of cognitive interviewing. Public Opin Q., 71 287. 🔗 https://doi.org/10.1093/poq/nfm006
- Alaimo (1999). Importance of cognitive testing for survey items: an example from food security questionnaires. J Nutr Educ., 31 269. 🔗 https://doi.org/10.1016/S0022-3182(99)70463-2
- Willis (1994). Cognitive Interviewing and Questionnaire Design: A Training Manual. Cognitive Methods Staff Working Paper Series.
- Willis (2005). Cognitive Interviewing: A Tool for Improving Questionnaire Design. 🔗 https://doi.org/10.4135/9781412983655
- Tourangeau (2003). Cognitive aspects of survey measurement and mismeasurement. Int J Public Opin Res., 15 3. 🔗 https://doi.org/10.1093/ijpor/15.1.3
- Morris (2017). Development and validation of a novel scale for measuring interpersonal factors underlying injection drug using behaviours among injecting partnerships. Int J Drug Policy, 48 54. 🔗 https://doi.org/10.1016/j.drugpo.2017.05.030
- Harris (2009). Research electronic data capture (REDCap)—a metadata-driven methodology and workflow process for providing translational research informatics support. J Biomed Inform., 42 377. 🔗 https://doi.org/10.1016/j.jbi.2008.08.010
- GoldsteinM BenerjeeR KilicT The World Bank Development ImpactPaper v Plastic Part 1: The Survey Revolution Is in Progress2012
- Fanning (2014). A Comparison of tablet computer and paper-based questionnaires in healthy aging research. JMIR Res Protoc., 3 🔗 https://doi.org/10.2196/resprot.3291
- Greenlaw (2009). A Comparison of web-based and paper-based survey methods: testing assumptions of survey mode and response cost. Eval Rev., 33 464. 🔗 https://doi.org/10.1177/0193841X09340214
- MacCallum (1999). Sample size in Factor analysis. Psychol Methods, 4 84. 🔗 https://doi.org/10.1037/1082-989X.4.1.84
- Nunnally (1978). Pyschometric Theory.
- Guadagnoli (1988). Relation of sample size to the stability of component patterns. Am Psychol Assoc., 103 265. 🔗 https://doi.org/10.1037/0033-2909.103.2.265
- Comrey (1988). Factor-analytic methods of scale development in personality and clinical psychology. Am Psychol Assoc., 56 754.
- Comrey (1992). A First Cours in Factor analysis.
- Ong (2014). A Primer to Bootstrapping and an Overview of doBootstrap.
- Osborne (2004). Sample size and subject to item ratio in principal components analysis. Pract Assess Res Eval, 99 1.
- Ebel (1979). Essentials of Educational Measurement.
- Hambleton (1993). Educ Meas Issues Pract., 12 38. 🔗 https://doi.org/10.1111/j.1745-3992.1993.tb00543.x
- Raykov (2015). Scale Construction and Development. Lecture Notes. Measurement and Quantitative Methods.
- Whiston (2008). Principles and Applications of Assessment in Counseling,
- Brennan (1972). A generalized upper-lower item discrimination index. Educ Psychol Meas., 32 289. 🔗 https://doi.org/10.1177/001316447203200206
- Popham (1969). Implications of criterion-referenced measurement. J Educ Meas., 6 1. 🔗 https://doi.org/10.1111/j.1745-3984.1969.tb00654.x
- Relationship between item difficulty and discrimination indices in true/false-type multiple choice questions of a para-clinical multidisciplinary paper6771 RasiahS-MS IsaiahR 16565756Ann Acad Med Singap352006
- Demars (2010). Item Respons Theory. 🔗 https://doi.org/10.1093/acprof:oso/9780195377033.001.0001
- Lord (1980). Applications of Item Response Theory to Practical Testing Problems.
- Bazaldua (2017). Assessing the performance of Classical Test Theory item discrimination estimators in Monte Carlo simulations. Asia Pac Educ Rev., 18 585. 🔗 https://doi.org/10.1007/s12564-017-9507-4
- Piedmont (2014). Inter-item correlations. 3303. 🔗 https://doi.org/10.1007/978-94-007-0753-5_1493
- Tarrant (2009). An assessment of functioning and non-functioning distractors in multiple-choice questions: a descriptive analysis. BMC Med Educ., 9 40. 🔗 https://doi.org/10.1186/1472-6920-9-40
- Fulcher (2012). The Routledge Handbook of Language Testing.
- Cizek (1994). Further investigation of nonfunctioning options in multiple-choice test items. Educ Psychol Meas., 54 861. 🔗 https://doi.org/10.1177/0013164494054004002
- Haladyna (1989). Validity of a taxonomy of multiple-choice item-writing rules. Appl Meas Educ., 2 51. 🔗 https://doi.org/10.1207/s15324818ame0201_4
- Tappen (2011). Advanced Nursing Research.
- Enders (2009). The relative performance of full information maximum likelihood estimation for missing data in structural equation models. Struct Equ Model., 8 430. 🔗 https://doi.org/10.1207/S15328007SEM0803_5
- Kenward (2007). Multiple imputation: current perspectives. Stat Methods Med Res., 16 199. 🔗 https://doi.org/10.1177/0962280206075304
- Gottschall (2012). A Comparison of item-level and scale-level multiple imputation for questionnaire batteries. Multivar Behav Res., 47 1. 🔗 https://doi.org/10.1080/00273171.2012.640589
- Cattell (1966). The Scree test for the number of factors. Multivar Behav Res., 1 245. 🔗 https://doi.org/10.1207/s15327906mbr0102_10
- Horn (1965). A rationale and test for the number of factors in Factor analysis. Psychometrika, 30 179. 🔗 https://doi.org/10.1007/BF02289447
- Velicer (1976). Determining the number of components from the matrix of partial correlations. Psychometrika, 41 321. 🔗 https://doi.org/10.1007/BF02293557
- Lorenzo-Seva (2011). The hull method for selecting the number of common factors. Multivar Behav Res., 46 340. 🔗 https://doi.org/10.1080/00273171.2011.564527
- Jolijn Hendriks (2003). The five-factor personality inventory: cross-cultural generalizability across 13 countries. Eur J Pers., 17 347. 🔗 https://doi.org/10.1002/per.491
- Bond (2013). Applying the Rasch Model: Fundamental Measurement in the Human Sciences. 🔗 https://doi.org/10.4324/9781410614575
- Brown (2014). Confirmatory Factor analysis for Applied Research.
- Morin (2016). A bifactor exploratory structural equation modeling framework for the identification of distinct sources of construct-relevant psychometric multidimensionality. Struct Equ Model Multidiscip J., 23 116. 🔗 https://doi.org/10.1080/10705511.2014.961800
- Cochran (1952). The χ2 test of goodness of fit. Ann Math Stat., 23 315. 🔗 https://doi.org/10.1214/aoms/1177729380
- Brown (2014). Confirmatory Factor analysis for Applied Research.
- Tucker (1973). A reliability coefficient for maximum likelihood Factor analysis. Psychometrika, 38 1. 🔗 https://doi.org/10.1007/BF02291170
- Bentler (1980). Significance tests and goodness of fit in the analysis of covariance structures. Psychol Bull., 88 588. 🔗 https://doi.org/10.1037/0033-2909.88.3.588
- Bentler (1990). Comparative fit indexes in structural models. Psychol Bull., 107 238. 🔗 https://doi.org/10.1037/0033-2909.107.2.238
- Hu (1999). Cutoff criteria for fit indexes in covariance structure analysis: Conventional criteria versus new alternatives. Struct Equ Model Multidiscip J., 6 1. 🔗 https://doi.org/10.1080/10705519909540118
- JöreskogKG SörbomD LISREL 8.54. Structural Equation Modeling With the Simplis Command Language2004
- Browne (1993). Alternative ways of assessing model fit. 136.
- Yu (2002). Evaluating Cutoff Criteria of Model Fit Indices for Latent Variable Models With Binary and Continuous Outcomes.
- Gerbing (1996). Viability of exploratory Factor analysis as a precursor to confirmatory Factor analysis. Struct Equ Model Multidiscip J., 3 62. 🔗 https://doi.org/10.1080/10705519609540030
- Reise (2007). The role of the bifactor model in resolving dimensionality issues in health outcomes measures. Qual Life Res., 16 19. 🔗 https://doi.org/10.1007/s11136-007-9183-7
- Gibbons (1992). Full-information item bi-Factor analysis. Psychometrika, 57 423. 🔗 https://doi.org/10.1007/BF02295430
- Reise (2010). Bifactor models and rotations: exploring the extent to which multidimensional data yield univocal scale scores. J Pers Assess., 92 544. 🔗 https://doi.org/10.1080/00223891.2010.496477
- Brunner (2012). A Tutorial on hierarchically structured constructs. J Pers., 80 796. 🔗 https://doi.org/10.1111/j.1467-6494.2011.00749.x
- Vandenberg (2000). A review and synthesis of the measurement invariance literature: suggestions, practices, and recommendations for organizational research – Robert J. Vandenberg, Charles E. Lance, 2000. Organ Res Methods, 3 4. 🔗 https://doi.org/10.1177/109442810031002
- Sideridis Multi-population invariance with dichotomous measures: combining multi-group and MIMIC methodologies in evaluating the general aptitude test in the arabic language – Georgios D. Sideridis, Ioannis Tsaousis, Khaleel A. Al-harbi, 2015. J Psychoeduc Assess., 33 568. 🔗 https://doi.org/10.1177/0734282914567871
- Joreskog (1973). A general method for estimating a linear equation system. 85.
- Kim (2017). Measurement invariance testing with many groups: a comparison of five approaches. Struct Equ Model Multidiscip J., 24 524. 🔗 https://doi.org/10.1080/10705511.2017.1304822
- MuthénB. AsparouhovT BSEM Measurement Invariance Analysis2017
- Asparouhov Multiple-group Factor analysis alignment. Struct Equ Model., 21 495. 🔗 https://doi.org/10.1080/10705511.2014.919210
- Reise (1993). Confirmatory Factor analysis and item response theory: two approaches for exploring measurement invariance. Psychol Bull., 114 552. 🔗 https://doi.org/10.1037/0033-2909.114.3.552
- Pushpanathan (2018). Beyond Factor analysis: multidimensionality and the Parkinson's disease sleep scale-revised. PLoS ONE, 13 🔗 https://doi.org/10.1371/journal.pone.0192394
- Armor (1973). Theta reliability and factor scaling. Sociol Methodol., 5 17. 🔗 https://doi.org/10.2307/270831
- Porta (2008). A Dictionary of Epidemiology.
- Cronbach (1951). Coefficient alpha and the internal structure of tests. Psychometrika, 16 297. 🔗 https://doi.org/10.1007/BF02310555
- Zumbo (2007). Ordinal versions of coefficients alpha and theta for likert rating scales. J Mod Appl Stat Methods, 6 21. 🔗 https://doi.org/10.22237/jmasm/1177992180
- Estimating ordinal reliability for Likert type and ordinal item response data: a conceptual, empirical, and practical guide113 GadermannAM GuhnM ZumboB Pract Assess Res Eval172012
- McDonald (1999). Test Theory: A Unified Treatment.
- Revelle (1979). Hierarchical cluster analysis and the internal structure of tests. Multivar Behav Res., 14 57. 🔗 https://doi.org/10.1207/s15327906mbr1401_4
- Revelle (2009). Coefficients alpha, beta, omega, and the glb: comments on Sijtsma. Psychometrika, 74 145. 🔗 https://doi.org/10.1007/s11336-008-9102-z
- Bernstein (1994). Pyschometric Theory.
- Weir (2005). JP: Quantifying test-retest reliability using the intraclass correlation coefficient and the SEM. J Strength Con Res., 19 231. 🔗 https://doi.org/10.1519/15184.1
- Rousson (2002). Assessing intrarater, interrater and test–retest reliability of continuous measurements. Stat Med., 21 3431. 🔗 https://doi.org/10.1002/sim.1253
- Churchill (1979). A paradigm for developing better measures of marketing constructs. J Mark Res., 16 64. 🔗 https://doi.org/10.2307/3150876
- Bland (1990). A note on the use of the intraclass correlation coefficient in the evaluation of agreement between two methods of measurement. Comput Biol Med., 20 337. 🔗 https://doi.org/10.1016/0010-4825(90)90013-F
- Hebert (1991). The inappropriateness of conventional use of the correlation coefficient in assessing Validity and reliability of dietary assessment methods. Eur J Epidemiol., 7 339. 🔗 https://doi.org/10.1007/BF00144997
- McPhail (2007). Alternative Validation Strategies: Developing New and Leveraging Existing Validity Evidence.
- DrayS DunschF HolmlundM The World Bank Development ImpactElectronic Versus Paper-Based Data Collection: Reviewing the Debate2016
- Ellen (2002). A randomized comparison of A-CASI and phone interviews to assess STD/HIV-related risk behaviors in teens. J Adolesc Health, 31 26. 🔗 https://doi.org/10.1016/S1054-139X(01)00404-9
- Chesney (2006). A Validity and reliability study of the coping self-efficacy scale. Br J Health Psychol., 11 421. 🔗 https://doi.org/10.1348/135910705X53155
- Thurstone (1947). Multiple-Factor analysis.
- Fan (1998). Item response theory and Classical Test Theory: an empirical comparison of their item/person statistics. Educ Psychol Meas., 58 357. 🔗 https://doi.org/10.1177/0013164498058003001
- Glockner-Rist (2003). The best of both worlds: Factor analysis of dichotomous data using item response theory and structural equation modeling. Struct Equ Model Multidiscip J., 10 544. 🔗 https://doi.org/10.1207/S15328007SEM1004_4
- Keeves (2005). Applied Rasch Measurement: A Book of Exemplars: Papers in Honour of John P. Keeves.
- Cappelleri (2014). Overview of Classical Test Theory and item response theory for quantitative assessment of items in developing patient-reported outcome measures. Clin Ther., 36 648. 🔗 https://doi.org/10.1016/j.clinthera.2014.04.006
- Harvey (1999). Item response theory. Couns Psychol., 27 353. 🔗 https://doi.org/10.1177/0011000099273004
- Cook (2009). Having a fit: impact of number of items and distribution of data on traditional criteria for assessing IRT's unidimensionality assumption. Qual. Life Res, 18 447. 🔗 https://doi.org/10.1007/s11136-009-9464-4
- Greca (1993). Social anxiety scale for children-revised: factor structure and concurrent Validity. J Clin Child Psychol., 22 17. 🔗 https://doi.org/10.1207/s15374424jccp2201_2
- Frongillo (2004). Technical Guide to Developing a Direct, Experience-Based Measurement Tool for Household Food Insecurity.
Cite this article
Mohammed looti (2026). Best Practices for Developing and Validating Scales (Primer). PSYCHOLOGICAL SCALES. Retrieved from https://scales.arabpsychology.com/s/best-practices-for-developing-and-validating-scales-primer/
Mohammed looti. "Best Practices for Developing and Validating Scales (Primer)." PSYCHOLOGICAL SCALES, 14 Aug. 2026, https://scales.arabpsychology.com/s/best-practices-for-developing-and-validating-scales-primer/.
Mohammed looti. "Best Practices for Developing and Validating Scales (Primer)." PSYCHOLOGICAL SCALES, 2026. https://scales.arabpsychology.com/s/best-practices-for-developing-and-validating-scales-primer/.
Mohammed looti (2026) 'Best Practices for Developing and Validating Scales (Primer)', PSYCHOLOGICAL SCALES. Available at: https://scales.arabpsychology.com/s/best-practices-for-developing-and-validating-scales-primer/.
[1] Mohammed looti, "Best Practices for Developing and Validating Scales (Primer)," PSYCHOLOGICAL SCALES, vol. X, no. Y, ص Z-Z, August, 2026.
Mohammed looti. Best Practices for Developing and Validating Scales (Primer). PSYCHOLOGICAL SCALES. 2026;vol(issue):pages.