
Table of Contents
Residuals are fundamental components in statistical modeling, particularly within regression analysis. They represent the difference between the observed value and the value predicted by the model. While standard residuals provide a basic measure of error, the effectiveness of any regression model can be significantly skewed by influential data points, commonly known as outliers. To robustly assess the impact of these individual observations, statisticians rely on specialized metrics, chief among them being the studentized residual. This metric refines the standard residual by accounting for the varying precision across different data points.
In the Python ecosystem, performing rigorous statistical diagnostics is often achieved using the statsmodels library, a powerful tool designed for estimating statistical models and performing tests. Calculating studentized residuals involves a process where we first fit our linear model—typically using Ordinary Least Squares (OLS)—and then apply a specific function to extract these adjusted residuals. The core utility of the studentized residual is to standardize the error in such a way that its magnitude directly indicates how unusual the corresponding observation is, relative to the rest of the dataset and the fitted model structure. An observation with a large studentized residual signals potential undue influence on the regression coefficients, making its identification critical for ensuring model validity and reliability.
A studentized residual is an essential diagnostic measure, calculated as a residual divided by an unbiased estimate of its own standard deviation. Unlike standardized residuals, this estimate is derived from a model fit that excludes the observation in question, providing a more robust measure of influence.
In practice, statistical guidelines suggest that any observation in a dataset that has a studentized residual greater than an absolute value of 3 is considered a potential outlier. Such observations should be investigated further as they may unduly influence the regression parameters.
We can quickly and accurately obtain the studentized residuals of a regression model in Python by leveraging the OLSResults.outlier_test() function provided by the statsmodels library, which is specifically designed for such diagnostic testing.
The syntax for this function is highly intuitive: OLSResults.outlier_test()
Here, OLSResults refers to the results object returned after a linear model has been fitted using the ols() function from statsmodels, encapsulating all necessary model statistics for the diagnostic test.
Introduction to Residuals and Influence
In the context of linear regression, a residual is defined as the vertical distance between a data point and the regression line. Mathematically, it is expressed as $e_i = y_i – hat{y}_i$, where $y_i$ is the observed response value and $hat{y}_i$ is the value predicted by the model for the $i$-th observation. These raw residuals are crucial for understanding the model’s goodness of fit, but they suffer from a limitation: their variance is often not constant across all observations, leading to heteroscedasticity. This non-constant variance means that residuals closer to the mean of the predictor variable tend to have smaller variances than those at the extremes. Therefore, judging influence purely based on the raw residual magnitude can be misleading, especially when dealing with data points positioned far from the center of the explanatory variables.
The concept of influence in regression focuses on how much a single data point affects the overall estimated parameters, such as the slope and intercept. An observation might have a small residual but still exert significant leverage if it is far removed from the bulk of the data along the predictor axis. Conversely, an observation might have a large raw residual but little leverage if its predictor value is near the mean. To properly diagnose potential issues, we need a standardized measure that adjusts the residual magnitude based on the leverage of that specific data point. This is where standardized and, more specifically, studentized residuals come into play, offering a refined method for identifying unusual or problematic observations that could distort the regression relationship.
When preparing data for statistical modeling, addressing influential points is paramount. Failing to detect and manage high-leverage outliers can lead to biased coefficient estimates, inaccurate standard errors, and ultimately, flawed inferential conclusions. The use of studentized residuals provides a robust statistical test for whether an observation’s residual is significantly larger than expected, given the structure of the data and the model fit. By normalizing the residual using an estimate of its own standard deviation, we effectively turn the residual into a value that approximates a standard normal distribution, allowing for simpler interpretation based on common statistical thresholds.
Understanding Studentized Residuals vs. Standardized Residuals
It is important to differentiate between standardized and studentized residuals, as they serve different purposes in diagnostics. A standardized residual is calculated by dividing the raw residual by the estimated standard deviation of all residuals. While this is an improvement over raw residuals, the standard deviation estimate used in the denominator still includes the specific observation being evaluated. This inclusion slightly pulls the regression line towards the observation, artificially making the residual appear smaller than it truly is, especially for extreme data points. This slight dampening effect means that standardized residuals might underestimate the severity of extreme outliers, masking their true influence.
The studentized residual (also known as the externally studentized residual or deleted residual) resolves this issue by employing a more rigorous approach. It divides the raw residual by an estimate of its standard deviation calculated from a model fitted to all data points except the one being evaluated. This process, often referred to as “deletion,” ensures that the estimate of the error variance is independent of the observation in question, providing a truly unbiased measure of how far that point lies from the relationship defined by the rest of the data. This technique makes the studentized residual a much more sensitive and reliable statistic for identifying potential leverage points and severe deviations than its standardized counterpart.
Mathematically, the studentized residual follows a t-distribution with $n-p-1$ degrees of freedom, where $n$ is the number of observations and $p$ is the number of predictors. This distributional property is crucial because it allows us to perform formal hypothesis testing. As mentioned earlier, a widely adopted rule of thumb suggests that any observation with a studentized residual having an absolute value greater than 3 is a strong candidate for being classified as a severe outlier. Such extreme values indicate a high probability that the observation does not belong to the population characterized by the majority of the data and may require special consideration or robust modeling techniques.
The Role of the statsmodels Library in Regression Analysis
When conducting statistical modeling in Python, the statsmodels library provides analysts with tools for rigorous statistical inference and detailed diagnostics, often comparable to dedicated statistical software packages. Unlike libraries focused on predictive performance, statsmodels emphasizes accurate parameter estimation, standard error calculation, and post-estimation testing for model validation. It is the ideal choice for performing diagnostics like calculating studentized residuals, leveraging its robust implementations of linear models.
To utilize this functionality, we first define and fit a linear model, typically using the ols() function accessed via the statsmodels.formula.api module. Once the model estimation is complete, the function returns an instance of the OLSResults class. This object acts as a container for all the model outputs, including coefficients, covariance matrices, and the critical diagnostic methods needed for influence analysis.
The specific function that automates the calculation of studentized residuals is OLSResults.outlier_test(). This method efficiently accesses the internal structure of the fitted model to perform the deletion necessary for external studentization. It returns a structured output, often a pandas DataFrame, that includes not only the calculated studentized residual for each observation but also the associated statistical significance metrics, simplifying the process of identifying truly influential or outlying data points within the regression framework.
Step-by-Step Example: Data Preparation and OLS Model Fitting
To demonstrate the calculation process practically, we will set up a scenario using a small, illustrative dataset. Our goal is to fit a simple linear model predicting a ‘rating’ based on ‘points’. The initial steps require importing the key data science libraries: NumPy for numerical operations, Pandas for constructing and managing the dataset, and the necessary modules from statsmodels for the regression analysis.
The subsequent step involves creating a DataFrame to hold our sample observations. We define ten pairs of ‘rating’ and ‘points’ values. Following data creation, we use the ols() function, employing formula syntax (‘rating ~ points’), which clearly specifies the dependent and independent variables. The .fit() method then executes the Ordinary Least Squares estimation, storing the complete results in the model object.
This phase is the foundational requirement for all subsequent diagnostic testing. The structure and parameters derived from this OLS fitting are necessary inputs for the studentized residual calculation, ensuring that the influence metrics are based on the established relationship between the predictor and response variables.
# Import necessary packages and functions
import numpy as np
import pandas as pd
import statsmodels.api as sm
from statsmodels.formula.api import ols

# Create dataset
df = pd.DataFrame({'rating': [90, 85, 82, 88, 94, 90, 76, 75, 87, 86],
                   'points': [25, 20, 14, 16, 27, 20, 12, 15, 14, 19]})

# Fit simple linear regression model
model = ols('rating ~ points', data=df).fit()
Calculating and Interpreting Studentized Residuals in Python
With the model object successfully created, calculating the studentized residuals is a single command. We execute the outlier_test() method on the fitted model, which immediately generates the necessary diagnostic statistics for all observations. This function handles the complex statistical calculations internally, providing a clean, accessible output ready for interpretation.
We store the results in the stud_res variable and print the DataFrame to the console. This tabular output provides the precise studentized residual value for each observation, allowing for a quick check against the critical threshold of $|text{studentized residual}| > 3$.
# Calculate studentized residuals
stud_res = model.outlier_test()

# Display studentized residuals and associated diagnostics
print(stud_res)

    student_resid	 unadj_p	 bonf(p)
0	-0.486471	0.641494	1.000000
1	-0.491937	0.637814	1.000000
2 	 0.172006	0.868300	1.000000
3	 1.287711	0.238781	1.000000
4	 0.106923	0.917850	1.000000
5	 0.748842	0.478355	1.000000
6	-0.968124	0.365234	1.000000
7	-2.409911	0.046780	0.467801
8	 1.688046	0.135258	1.000000
9	-0.014163	0.989095	1.000000
This DataFrame displays three crucial diagnostic values for each observation:
- The
student_resid: The calculated studentized residual, reflecting the standardized distance of the observation from the regression line derived without that observation. - The
unadj_p: The unadjusted p-value associated with the hypothesis test that the residual mean is zero for that observation. - The
bonf(p): The Bonferroni-corrected p-value, accounting for the problem of multiple comparisons across the dataset.
From the output, we can observe that the studentized residual for the first observation is -0.486471, while the residual for the second observation is -0.491937. Most importantly, we scan the student_resid column for any values approaching or exceeding 3 in absolute terms. In this dataset, observation 7 has the largest magnitude at -2.409911, which, while high relative to the others, falls below the standard critical threshold of 3, suggesting no immediate, extreme outliers are present based purely on the magnitude criterion.
Visualizing Residuals for Outlier Detection
Visualizing diagnostic statistics provides a powerful complement to numerical inspection. A plot of studentized residuals versus the predictor variable helps confirm assumptions and visually identify points that deviate significantly from the central tendency of zero. This graphical step often provides instant clarity regarding potential influential points.
To generate this visualization, we import the Matplotlib library’s pyplot module. We then prepare the data by extracting the predictor variable values (‘points’) for the x-axis and the calculated studentized residuals (‘student_resid’) for the y-axis.
The scatterplot is created using these variables, and two critical elements are added to aid interpretation: a horizontal dashed line at $y=0$ to represent the expected residual mean, and the axis labels (‘Points’ and ‘Studentized Residuals’) to ensure clarity. In detailed analysis, horizontal lines at $y=3$ and $y=-3$ are often added to visually mark the standard outlier threshold.
import matplotlib.pyplot as plt

# Define predictor variable values and studentized residuals
x = df['points']
y = stud_res['student_resid']

# Create scatterplot of predictor variable vs. studentized residuals
plt.scatter(x, y)
plt.axhline(y=0, color='black', linestyle='--')
plt.xlabel('Points')
plt.ylabel('Studentized Residuals')
The resulting plot helps to confirm the findings derived from the numerical data inspection:
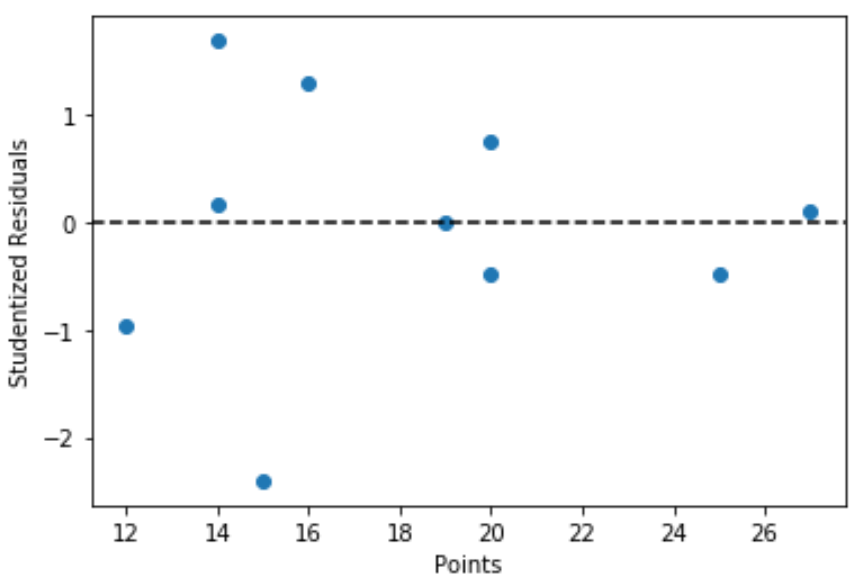
From the plot, we can visually confirm that none of the observations deviate far enough from the zero line to suggest an extreme outlier; specifically, none of the observations have a studentized residual with an absolute value greater than 3. This graphical evidence supports the conclusion that the relationship defined by the linear model is not severely distorted by any single, highly influential data point within this sample dataset.
Advanced Interpretation: P-Values and Bonferroni Correction
A thorough diagnostic procedure extends beyond simply checking the magnitude of the studentized residual; it involves formal hypothesis testing using the provided p-values. The OLSResults.outlier_test() method furnishes both unadjusted and Bonferroni-corrected p-values, which are essential for making statistically sound judgments about outlier status. These tests evaluate the hypothesis that the residual error for a specific observation is consistent with the error distribution of the overall sample.
The unadjusted p-value (unadj_p) tests the residual for that single observation. If this value is below a predefined significance level, typically $alpha = 0.05$, we would initially consider the point an outlier. However, performing many such individual tests introduces a high risk of making a Type I error (false positive) due to the problem of multiple comparisons. The more observations we test, the higher the probability that one of them will appear significant purely by chance.
To maintain the statistical integrity of the analysis, the Bonferroni correction is applied. This method controls the family-wise error rate by adjusting the individual test p-values upward, requiring a much stronger level of evidence to declare an observation statistically significant. The bonf(p) column in the output DataFrame provides this corrected p-value. For robust outlier identification, we rely on this corrected value: an observation is deemed a statistically significant outlier only if its Bonferroni correction p-value is less than the desired significance level (e.g., $0.05$).
Consider observation 7 from our example: its unadjusted p-value was 0.046780, which narrowly crosses the $alpha=0.05$ threshold. However, its Bonferroni-corrected p-value is significantly higher at 0.467801. Because this corrected value is much greater than $0.05$, we conclude that, when accounting for the entire set of comparisons, observation 7 is not a statistically significant outlier. This powerful diagnostic capability provided by statsmodels ensures that outlier identification is not based on spurious findings resulting from inflated error rates.
Conclusion and Next Steps
Mastering the calculation and interpretation of studentized residuals is a cornerstone of rigorous data analysis in Python. By correctly employing the statsmodels library and its specialized OLSResults.outlier_test() method, practitioners can accurately assess the influence exerted by individual data points, moving beyond simplistic raw error measures. This detailed approach is critical for ensuring that any conclusions drawn from regression models are statistically sound and robust against the detrimental effects of influential outliers.
We have successfully navigated the complete process: establishing the data, fitting the Ordinary Least Squares model, generating the studentized residuals, and performing both numerical and visual diagnostics. The combination of using the absolute magnitude threshold (3) and the formal statistical test incorporating the Bonferroni correction provides a comprehensive safety net against misidentifying normal noise as highly influential data.
For those advancing their diagnostic capabilities, the next logical steps involve integrating other high-leverage influence metrics. Measures such as Cook’s Distance and DFFITS offer alternative perspectives on influence, quantifying how much the model parameters shift when an observation is removed. Combining insights from studentized residuals with these other diagnostic tests ensures a comprehensive evaluation of model stability and data integrity, leading to more trustworthy statistical models and better decision-making.
How to Perform Simple Linear Regression in Python
How to Perform Multiple Linear Regression in Python
How to Create a Residual Plot in Python
Cite this article
stats writer (2025). How to Calculate Studentized Residuals in Python. PSYCHOLOGICAL SCALES. Retrieved from https://scales.arabpsychology.com/stats/how-to-calculate-studentized-residuals-in-python/
stats writer. "How to Calculate Studentized Residuals in Python." PSYCHOLOGICAL SCALES, 17 Dec. 2025, https://scales.arabpsychology.com/stats/how-to-calculate-studentized-residuals-in-python/.
stats writer. "How to Calculate Studentized Residuals in Python." PSYCHOLOGICAL SCALES, 2025. https://scales.arabpsychology.com/stats/how-to-calculate-studentized-residuals-in-python/.
stats writer (2025) 'How to Calculate Studentized Residuals in Python', PSYCHOLOGICAL SCALES. Available at: https://scales.arabpsychology.com/stats/how-to-calculate-studentized-residuals-in-python/.
[1] stats writer, "How to Calculate Studentized Residuals in Python," PSYCHOLOGICAL SCALES, vol. X, no. Y, ص Z-Z, December, 2025.
stats writer. How to Calculate Studentized Residuals in Python. PSYCHOLOGICAL SCALES. 2025;vol(issue):pages.